Free Auto-Generate Captions from Audio or Video — Browser-Based Whisper Guide
A deep guide to VideoBuff's auto-caption feature, covering the technical setup, the step-by-step workflow, and how it compares with cloud-based alternatives. OpenAI Whisper Large v3 Turbo runs inside the browser and turns audio into Japanese or English captions without uploading anything to a server. Useful for meeting transcripts, podcast post-production, interview captioning, and short-form (9:16) social videos where data sensitivity matters. Includes karaoke captions that light up word by word, translation into English and other languages through the Claude integration, SRT / VTT / TXT export, and a live preview that streams captions as they're decoded. Runs in browsers with WebGPU (Chrome / Edge).
Why in-browser — how it works and what it protects
Most caption services send your audio to the cloud before running an AI model on it. That's convenient, but with internal meetings, interviews or anything personal, you may not want to hand the recording to a third party at all. NDA-bound interview audio, healthcare or legal conversations, unreleased internal discussions — for many of these, "it doesn't leave my machine" is a hard requirement.
VideoBuff's auto captions run an ONNX build of OpenAI Whisper Large v3 Turbo inside your browser with Hugging Face Transformers.js. The audio is processed only in browser memory and is never sent anywhere. Neither is the caption text it produces.
The only network use is fetching the model. On the first run, the model files (about 1.6 GB) download from Hugging Face and the program that runs the model downloads from jsDelivr (a content delivery network); both are stored in the browser cache (Cache API). Later runs load from the cache, so there's no download to wait for. The browser may clear that cache — for example when your disk runs low — in which case the model downloads again.
Separately, if captioning fails, the error details may be sent to the site-wide analytics (Google Analytics). They never include your audio or caption text.
Auto captions need WebGPU. Browsers that have it (Chrome / Edge) run the model on the GPU. Without WebGPU the model doesn't fit in memory, and captions can't be generated.
How to use it
- On the timeline, select the video or audio clip you want to caption
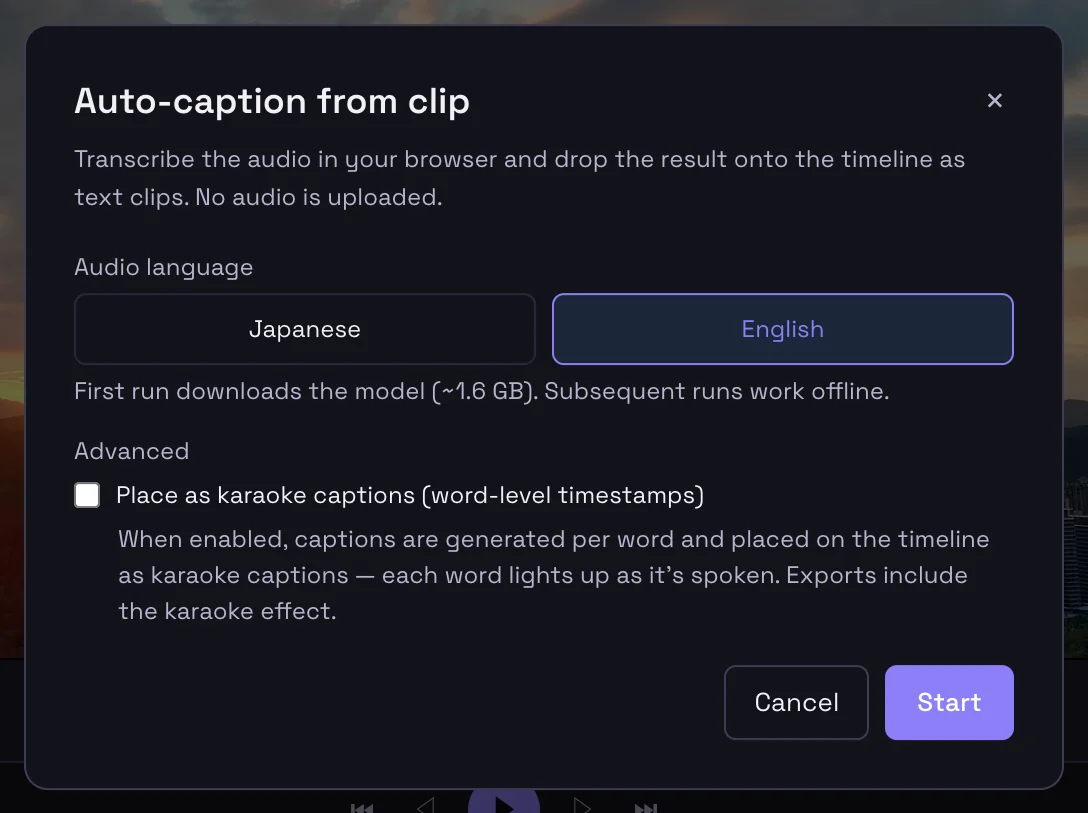
- In the Inspector's "Auto Caption" section, press the "Auto Caption…" button
- Choose the "Audio language" (Japanese or English). Captions come out in the spoken language
- For captions that light up word by word, turn on "Place as karaoke captions" under "Advanced"
- Press "Start". The first time, you'll see "Downloading model…" with its progress, then "Transcribing…" with the elapsed and estimated remaining time
- Review the captions in the list: click a line to fix it, or press × to remove it
- Press "Add to timeline" ("Add karaoke captions" in karaoke mode) and the captions are laid out on a new text track
The model starts loading in the background (downloading on the first run) as soon as the caption dialog opens.
If you use the Claude integration, you can also just say "add captions to this video." Language and karaoke captions can be requested in words. Ask for "English captions" and Claude translates the lines and rewrites them (other languages work too). Claude can then go on to fix wording or placement.
The model — Whisper Large v3 Turbo
Auto captions run on a single multilingual model: Whisper Large v3 Turbo. It's Whisper Large v3 with the decoder cut from 32 layers to 4 for speed, at 809M parameters. Accuracy is practical for both Japanese and English, including long interviews and material full of proper nouns.
Earlier versions let you choose between Whisper Small ("fast") and Turbo ("high quality"). Trying the small model and then re-running at high quality cost more than it saved, so they were merged into Turbo alone. There's no model to choose.
The model (about 1.6 GB) downloads once, on the first run. Karaoke captions use a separate build of the model that can report the timing of each word, so the first time you make karaoke captions there's a second download of about the same size.
Browsers with WebGPU (Chrome / Edge) run it on the GPU. Clear speech with little background noise gives the best results. Overlapping speakers, heavy jargon or poor recording conditions lead to more mistakes, so plan on a quick manual pass afterwards.
Captions in another language
Captions come out in the language being spoken. The model behind them, Whisper Large v3 Turbo, is tuned for speed and doesn't translate.
For captions in another language, ask through the Claude integration — "make these captions English." Claude translates the captions line by line and rewrites them, keeping their timing. It isn't limited to English: Chinese, Korean and other languages work too, and because Claude reads the context, casual speech and technical terms come out as natural captions.
To keep the original captions as well, generate the captions a second time (each "Add to timeline" puts them on a new text track) and have only one set translated — you'll get captions in two languages side by side.
Editing and downloading
When generation finishes, the captions appear in a list. Click a line to fix its text, or press × to delete it. Tidying up here saves cleanup later.
If you need a subtitle file, download SRT, VTT or TXT from below the list (available for regular captions; karaoke captions don't offer downloads). SRT is read by YouTube and most players, VTT is the format web pages use for video (the HTML5 track element), and TXT is a plain transcript without timestamps.
"Add to timeline" lays the captions out on a new text track. Font size and line length are chosen automatically from the canvas aspect ratio (16:9, 9:16 and so on), and long sentences are split across several captions. Once placed, each caption is an ordinary text clip — change its position, color, outline, font and transitions in the Inspector.
Live preview
While captions are being generated, finished lines appear as they come. You can see how far along it is and whether the opening is being heard correctly without waiting for the end — and decide early whether to change settings and rerun. The longer the audio, the more this helps.
Whisper works through the audio in 30-second pieces that overlap slightly. The live view shows those in-progress results as they are, so sentences may look cut off or duplicated. When it finishes, everything is stitched together and the overlaps removed, so the final captions aren't affected.
Karaoke captions — words light up as they're spoken
In the caption dialog, turn on "Place as karaoke captions" under "Advanced" to get captions that highlight each word as it's spoken during playback — the staple short-form "kinetic captions" look, made automatically and for free, entirely in your browser.
Regular captions place one text clip per sentence-sized segment. Karaoke mode instead splits them into short line-by-line clips, each carrying the time every word starts. When playback reaches that time, those characters switch to your chosen color.
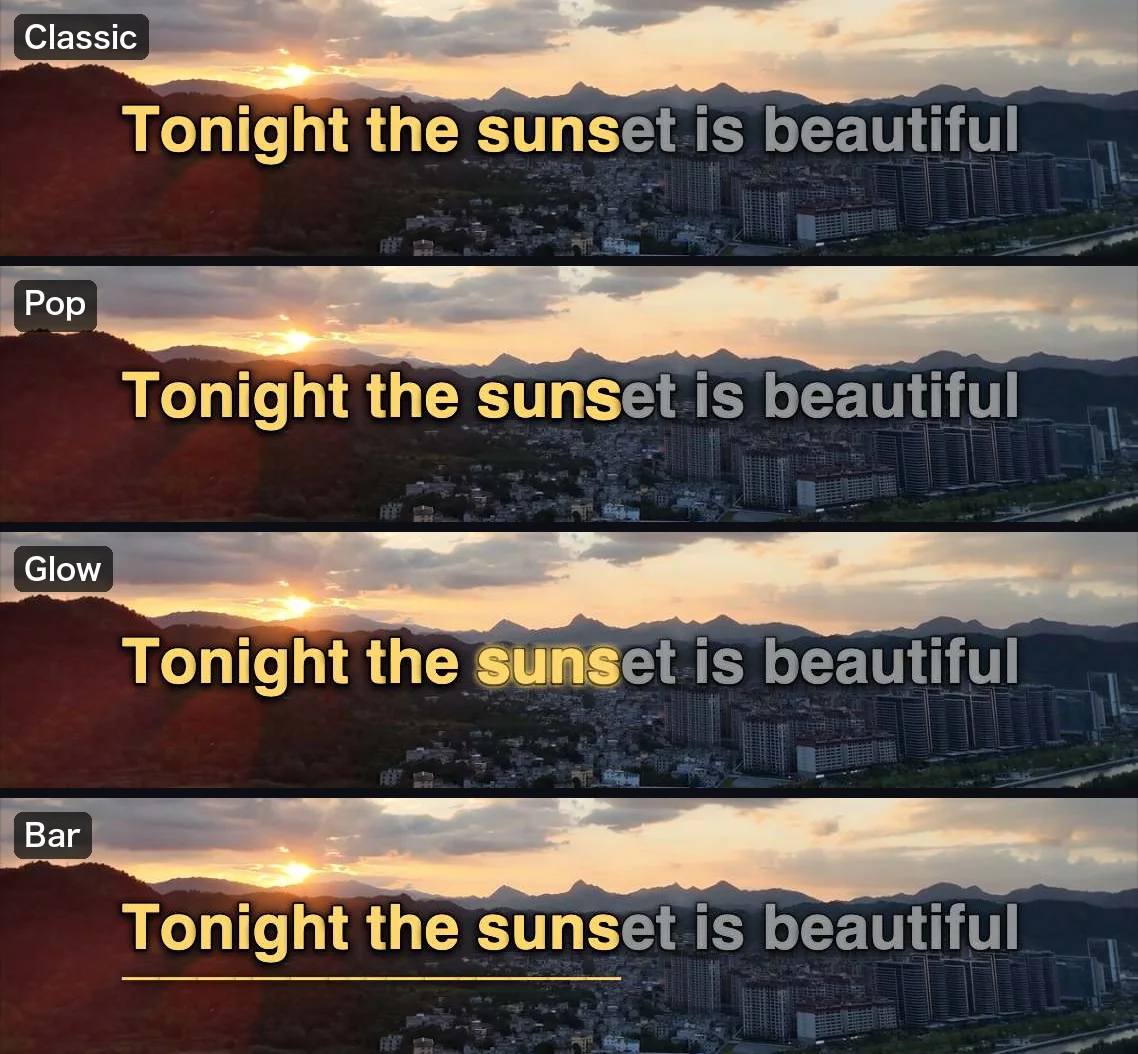
Four styles — pick one under "Karaoke style" when generating (you can change it later in the Inspector):
- Classic: sung words stay in the accent color — traditional karaoke fill
- Pop: the active character briefly scales up with a bounce
- Glow: the active character gets an accent-colored halo
- Bar: an accent-colored underline grows left to right under sung words
The color ("Karaoke color") is also set when generating and applied to every caption. Each clip's "Karaoke color" and "Karaoke style" can be changed individually in the Inspector afterwards.
How it works and what to expect — it uses Whisper's per-word timestamps (return_timestamps: 'word'). Whisper only times whole words, so within each word VideoBuff divides the duration evenly across its characters. For Japanese, Whisper returns small groups of characters as one "word", so the color moves in a natural phrase-by-phrase rhythm.
Fast speech or heavy background noise can throw the word timings off. Speech mixed with music is a weak spot. If you notice recognition errors or timing drift, fix or delete those lines in the results list before placing them on the timeline.
Same look in preview and export — preview and export share the same timing and color logic, so they look nearly identical, and the karaoke effect is baked into the exported video.
Performance tips
The first run spends time downloading the model; after that, captioning starts right away from the browser cache. Generation itself is also faster in browsers with WebGPU (Chrome / Edge).
Only the part of the clip you're actually using (its trimmed range) is captioned, so trimming away unneeded sections of a long recording first shortens processing.
If a recording — a meeting, say — has long silences at the start or end, asking Claude to "trim the silence at the start and end of each clip" through the Claude integration before captioning shortens the range that needs captioning, so it finishes sooner.
How VideoBuff differs from other auto-caption tools
Auto-captioning is now common across video editors and online services. What sets VideoBuff apart is this combination:
Stays in the browser Many cloud services upload your audio to their servers to process it. VideoBuff needs no install and no account — open the page and captions are made entirely inside your browser.
Part of the editor Caption-only tools that run Whisper in the browser leave you exporting SRT or VTT and bringing it into a separate editor. In VideoBuff the captions land directly on the timeline, ready for font, color, position and transition tweaks in the Inspector.
Free Captioning in VideoBuff is free, with no cap on minutes or runs. The only cost is your own computer's processing power.
You can check it yourself There's simply no mechanism that sends your audio anywhere, and you can confirm that in your browser's developer tools (the Network tab). That matters for NDA-bound material, healthcare, legal work and internal meetings.
Tradeoffs Because it runs on your own machine, there are no advanced extras such as speaker identification or custom dictionaries for proper nouns. If you need maximum accuracy and still want to keep audio off third-party servers, the next step is outside the browser — for example running Whisper on a server you control.
FAQ
Q. Can I use the captions commercially? A. Yes. VideoBuff charges nothing and places no restrictions on the captions you generate. The Whisper model used is MIT-licensed. See the "Runtime ML Models" section of the OSS Licenses page for details.
Q. How long an audio clip can I caption? A. There's no fixed limit, but longer audio takes more time and memory. For recordings over an hour or so, trim the clip to just the part you need first — only the trimmed range is processed.
Q. Does it work in browsers without WebGPU? A. No. Auto captions need WebGPU. Without it the model doesn't fit in memory, and you get an out-of-memory message instead of captions. Please use Chrome or Edge with WebGPU. Auto captions are also not available in Safari, because a Safari bug makes the page crash.
Q. Can I make captions in another language? A. The audio language can be Japanese or English, and captions come out in the spoken language. For captions in another language, have Claude translate them through the Claude integration, or download them as SRT and translate them with a translation tool.
Q. Where is the audio stored? A. Only in browser memory. It's never sent to VideoBuff's servers, Hugging Face or any other service. The only things downloaded and kept are the model files (and the program that runs them), stored in the browser's Cache API like any other cached web resource.
Q. Can I use it on a phone or tablet? A. The VideoBuff editor is built for desktop browsers and doesn't open on narrow phone screens. On iPhone and iPad it doesn't open in any browser. Given the model download (about 1.6 GB) and the processing load, a computer is the way to go.
Q. Does this work for vertical (9:16) short-form video? A. Yes. Caption font size and characters per line are set automatically from the canvas aspect ratio, so on 9:16 the lines are split shorter and stay inside the frame.
Q. How do I improve caption accuracy? A. The recording matters most: keep the mic close to the speaker and background noise low. Captions are made from the clip's original audio, so EQ or compression you apply to the clip in VideoBuff doesn't change the result. To clean up noise in an existing recording, process it in a separate audio editor (such as our sister tool AudioBuff) before importing. There's only one model, so there's no model to switch.
When the auto-caption button is missing (advanced)
Captions are made from audio, so the Inspector's "Auto Caption" section only appears when the selected clip has audio it can use.
Audio clip selected Always shown. Captions are placed to match the audio clip's position.
Video clip selected (linked to its audio) This is the state right after importing a video. The linked audio is used, and captions are placed to match the video clip's position. Usually this is all you need.
Video clip selected (unlinked, or its linked audio was deleted) The "Auto Caption" section is hidden. With video and audio separated, there's no single position to align the captions to. If the audio clip is still on the timeline after unlinking, select the audio clip instead — the captions are placed at the audio's position, so they stay in sync with the sound. If you want them aligned to the video, line up the start of the video and audio, then link them again with the link button in the timeline toolbar or "Link video and audio" in the right-click menu.
Audio-only files (m4a, mp3, wav, etc.) Clips imported as audio work the same way — handy for meeting recordings, podcasts and any source without video. Video files with no picture (such as audio-only MP4s) are imported as audio, so they work too.
If you want to reduce noise or even out the volume before captioning, clean the audio up first in a tool such as our sister service AudioBuff, then import the result into VideoBuff.